
We may earn a commission if you buy through links on this page. It never changes a score or a ranking. How we make money
The bottom line
Good value for teams comfortable with a technical setup; hosted team-seat costs are not published.
Crawl4AI turns web pages into Markdown and structured data for AI agents, RAG, and data pipelines. Small teams can try its hosted service on a free plan or run the open-source crawler themselves under Apache 2.0.
The hosted Starter plan lists $10 monthly or $100 per year, but Crawl4AI doesn’t publish per-seat pricing. Its value is clearest for teams that can work within credit limits or manage their own infrastructure.
Good fit if
- Technical teams building RAG pipelines
- Small projects with light scraping needs
- Teams comfortable self-hosting Python tools
Skip it if
- Teams needing published seat pricing
- Nontechnical users wanting guided setup
- High-volume work on a tight budget
ScoresHow it rates
What works
- Free hosted plan includes 1,000 credits monthly
- Self-hosted library is free under Apache 2.0
- Converts pages into Markdown and structured data
- Cloud includes scraping, search, and sourced answers
- Starter includes 10,000 credits monthly
What doesn't
- Hosted team-seat pricing is not published
- Credit consumption per task is not specified
- Self-hosting means paying infrastructure and proxy costs
- The hosted free plan has concurrency and rate limits
- Reddit discussion offers little detail on long-term use
01Who Crawl4AI is for
Crawl4AI is for small, technical teams that need website content for AI agents, RAG, or data pipelines—not every team that wants to save a few pages. It crawls websites and turns pages into clean Markdown or structured data. Extraction can use CSS, XPath, or LLM-based methods, according to the product description.
For a team of one to ten, the open-source library may suit a project with developer time and a willingness to manage infrastructure. Crawl4AI lists the library as free under Apache 2.0, but your team pays its own infrastructure, proxy, and LLM costs. Teams that would rather use a hosted API can start on the free Cloud plan or pay for Starter. That makes it worth considering for a small budget, though the vendor doesn’t publish per-seat pricing. If you need a simple point-and-click scraper or a clear price per teammate, check those details before committing.
02Crawl4AI free plan and trial
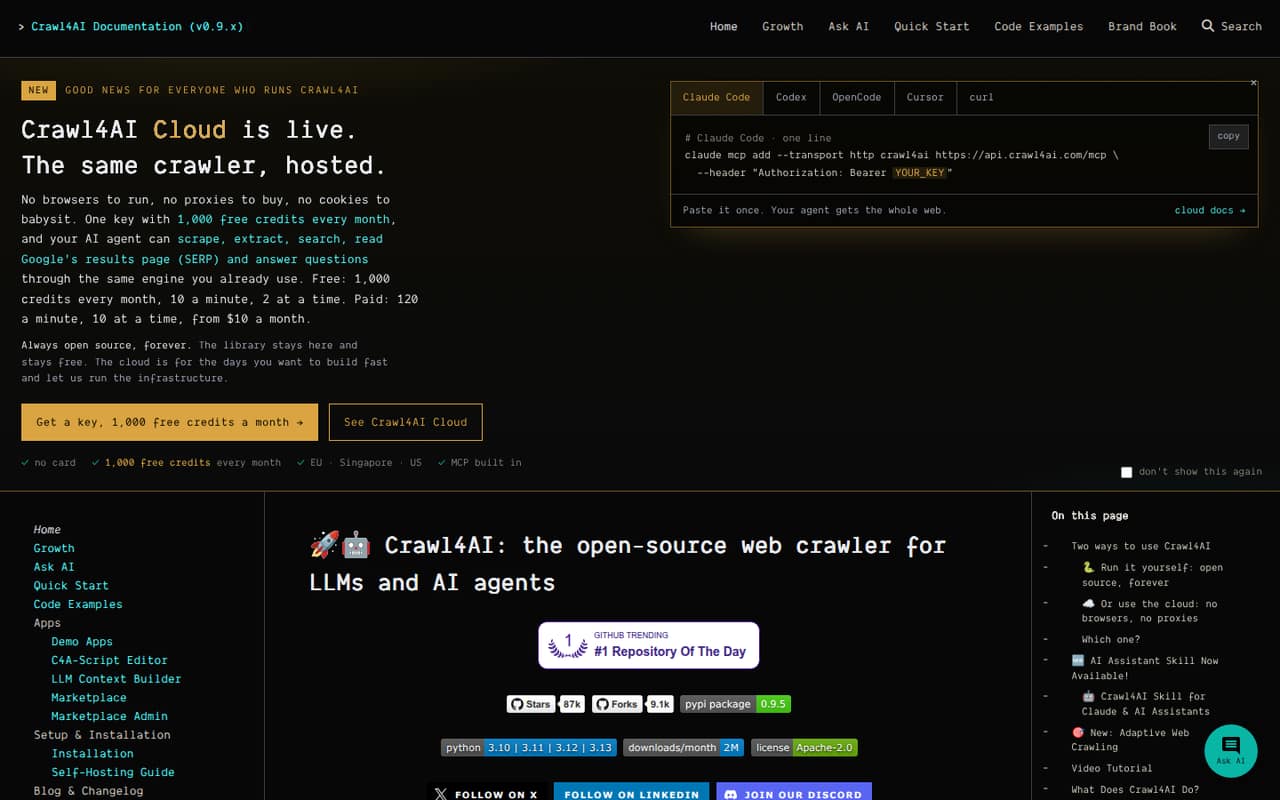
The hosted Free plan lists 1,000 credits monthly, a rate limit of 10 requests per minute, and up to 2 concurrent requests. The pricing information says no credit card is required. That is enough to explore low-volume crawling, but the vendor doesn’t publish how many credits a particular page or extraction task uses, so estimate your actual monthly capacity before relying on it.
There is also a separate 20-credit trial with no signup. For more hosted usage, Starter is the cheapest paid plan listed: $10 month to month, or $100 billed annually. Teams can avoid Cloud’s listed credit allowance by running the open-source crawler themselves, but infrastructure, proxy, and LLM costs are theirs. The free library is not the same as free hosting.
03What a small team pays for Crawl4AI
Crawl4AI Cloud pricing is listed by plan and monthly credits, not by seat. Starter costs $10 per month, or $100 per year, which works out to about $8.33 per month. That is the listed subscription price for one account; the vendor doesn’t publish whether three or five teammates can share it, or what those team sizes would cost. So we can’t give a reliable per-person total: ask Crawl4AI about seats and account access before budgeting.
For a small project, Starter includes 10,000 credits monthly, 120 requests per minute, and 10 concurrent requests. Extra credits cost $1 per 1,000. If usage grows, Builder lists 125,000 credits monthly for $99 month to month or $82.50 per month on annual billing, with extra credits at $0.79 per 1,000. The open-source library costs nothing to license, but you pay for your own infrastructure, proxies, and LLM use. Ask how credits are consumed by your planned workloads; that detail affects the real bill.
04Getting started with Crawl4AI
The setup effort depends on which version you choose. Crawl4AI says its open-source crawler can run with Python or Docker, while Cloud offers a hosted API. The library route asks your team to handle its own infrastructure, proxies, and LLM costs; Cloud avoids managing crawler hosting but uses monthly credits and request limits. We’d call this a technical setup rather than a plug-and-play tool, especially if your team is new to browser automation or extraction rules.
For day one, decide whether you need Markdown, structured extraction, or Cloud features such as web search and SERP data, then check how those fit your pipeline. Crawl4AI lists hooks, proxies, stealth modes, and session reuse for browser control. A Reddit user described an n8n workflow using Crawl4AI among SERP tools, but that does not establish a native integration or official connector. The docs’ exact setup time and onboarding support aren’t published, so confirm those if your team has no developer available.
05When small teams outgrow Crawl4AI
The first reason to move up is usage: Free lists 1,000 credits monthly, while Starter lists 10,000. Starter also caps requests at 120 per minute and concurrency at 10. Builder raises those limits to 125,000 credits, 600 requests per minute, and 20 concurrent requests, at $99 monthly or $82.50 per month on annual billing. Scale lists 750,000 credits and costs $499 monthly or $415.83 per month annually. Those higher tiers can make Cloud less attractive if your needs grow faster than your budget.
Team growth can expose a different gap: Crawl4AI doesn’t publish seat pricing or clarify team access in the plan details, so ask before rolling it out to more people. Self-hosting avoids Cloud credit quotas but shifts infrastructure, proxy, and LLM costs to your team. Reddit discussion is sparse and anecdotal: one post recommends Crawl4AI for documentation scraping, while another asks for comparisons. It offers little evidence about how well the product serves larger teams over time.
From the threadsWhat users say
The Reddit signal is limited and anecdotal, not a broad verdict on reliability or support. One post recommends Crawl4AI for documentation scraping, while another mentions it in a workflow and a separate thread asks about it.
If you're doing scraping with Fire Crawl to get Documentation, use "Crawl4AI" instead. It's better !
I built these mainly to speed up keyword research and competitor analysis for content creation
I was wondering if anyone has experience with browser-use and/or crawl4ai
Since my project is fairly in the beginning
Questions people ask
Is Crawl4AI free?
Yes. Crawl4AI lists an open-source library that is free under Apache 2.0, with unmetered use. You still pay for your own infrastructure, proxies, and LLM costs. Its hosted Cloud service also has a free plan with 1,000 credits monthly, 10 requests per minute, and 2 concurrent requests.
What does Crawl4AI Cloud Starter cost?
The pricing page lists Starter at $10 per month, or $100 per year, which is about $8.33 per month on annual billing. It includes 10,000 credits monthly, 120 requests per minute, and 10 concurrent requests. Extra credits are listed at $1 per 1,000.
Does Crawl4AI have per-seat pricing?
The listed Cloud plans are organized by credits and request limits, and per-seat pricing is not published. The vendor also doesn’t clarify whether several teammates can share one account. Ask about seats, permissions, and account access before calculating a three- or five-person budget.
Can I self-host Crawl4AI?
Yes. Crawl4AI says its open-source crawler can run with Python or Docker and is free under Apache 2.0. Self-hosting is unmetered, but your team pays for its own infrastructure, proxies, and LLM costs. Choose this route if you can manage those pieces.
What can Crawl4AI extract from websites?
Crawl4AI converts web pages into Markdown and can extract repeated patterns using CSS, XPath, or LLM-based methods. Its Cloud service also lists page scraping, batch or job workflows, web search, Google SERP data, and answers with sources.
Sources
- Crawl4AI homepage
- Crawl4AI pricing, compiled via web search from apis.io, crawl4ai.com, devtune.ai
- Reddit: Efficient SERP Analysis & Export Results to Google Sheets (SerpApi, Serper, Crawl4AI, Firecrawl)
- Reddit: If you're doing scraping with Fire Crawl to get Documentation, use "Crawl4AI" instead. It's better !
- Reddit: Browser-use vs Crawl4ai